
LLM
6 articles in LLM
A million-token context window did not make context management optional; it made the bill bigger. This post treats the context window as a budget, shows the arithmetic that makes agent runs expensive, and walks through the five techniques that actually move the needle: just-in-time retrieval, tool-result hygiene, compaction, memory files and sub-agents.
Context window một triệu token không làm việc quản lý context thành tuỳ chọn; nó chỉ làm hoá đơn to hơn. Bài này coi context window như một ngân sách, làm phép tính khiến mỗi lần chạy agent đắt đỏ, và đi qua năm kỹ thuật thực sự có tác dụng: retrieval đúng lúc, vệ sinh tool result, compaction, memory file và sub-agent.
Strip away the frameworks and every AI agent is the same small loop: call the model, run the tool it asked for, feed the result back, repeat. Here is that loop in plain Python, where it breaks in production, and the four controls I never ship without.
Bỏ framework ra, AI agent nào cũng chỉ là một vòng lặp nhỏ: gọi model, chạy tool nó yêu cầu, trả kết quả về, lặp lại. Bài này viết vòng lặp đó bằng Python thuần, chỉ ra chỗ nó vỡ khi lên production, và bốn thứ tôi không bao giờ ship thiếu.
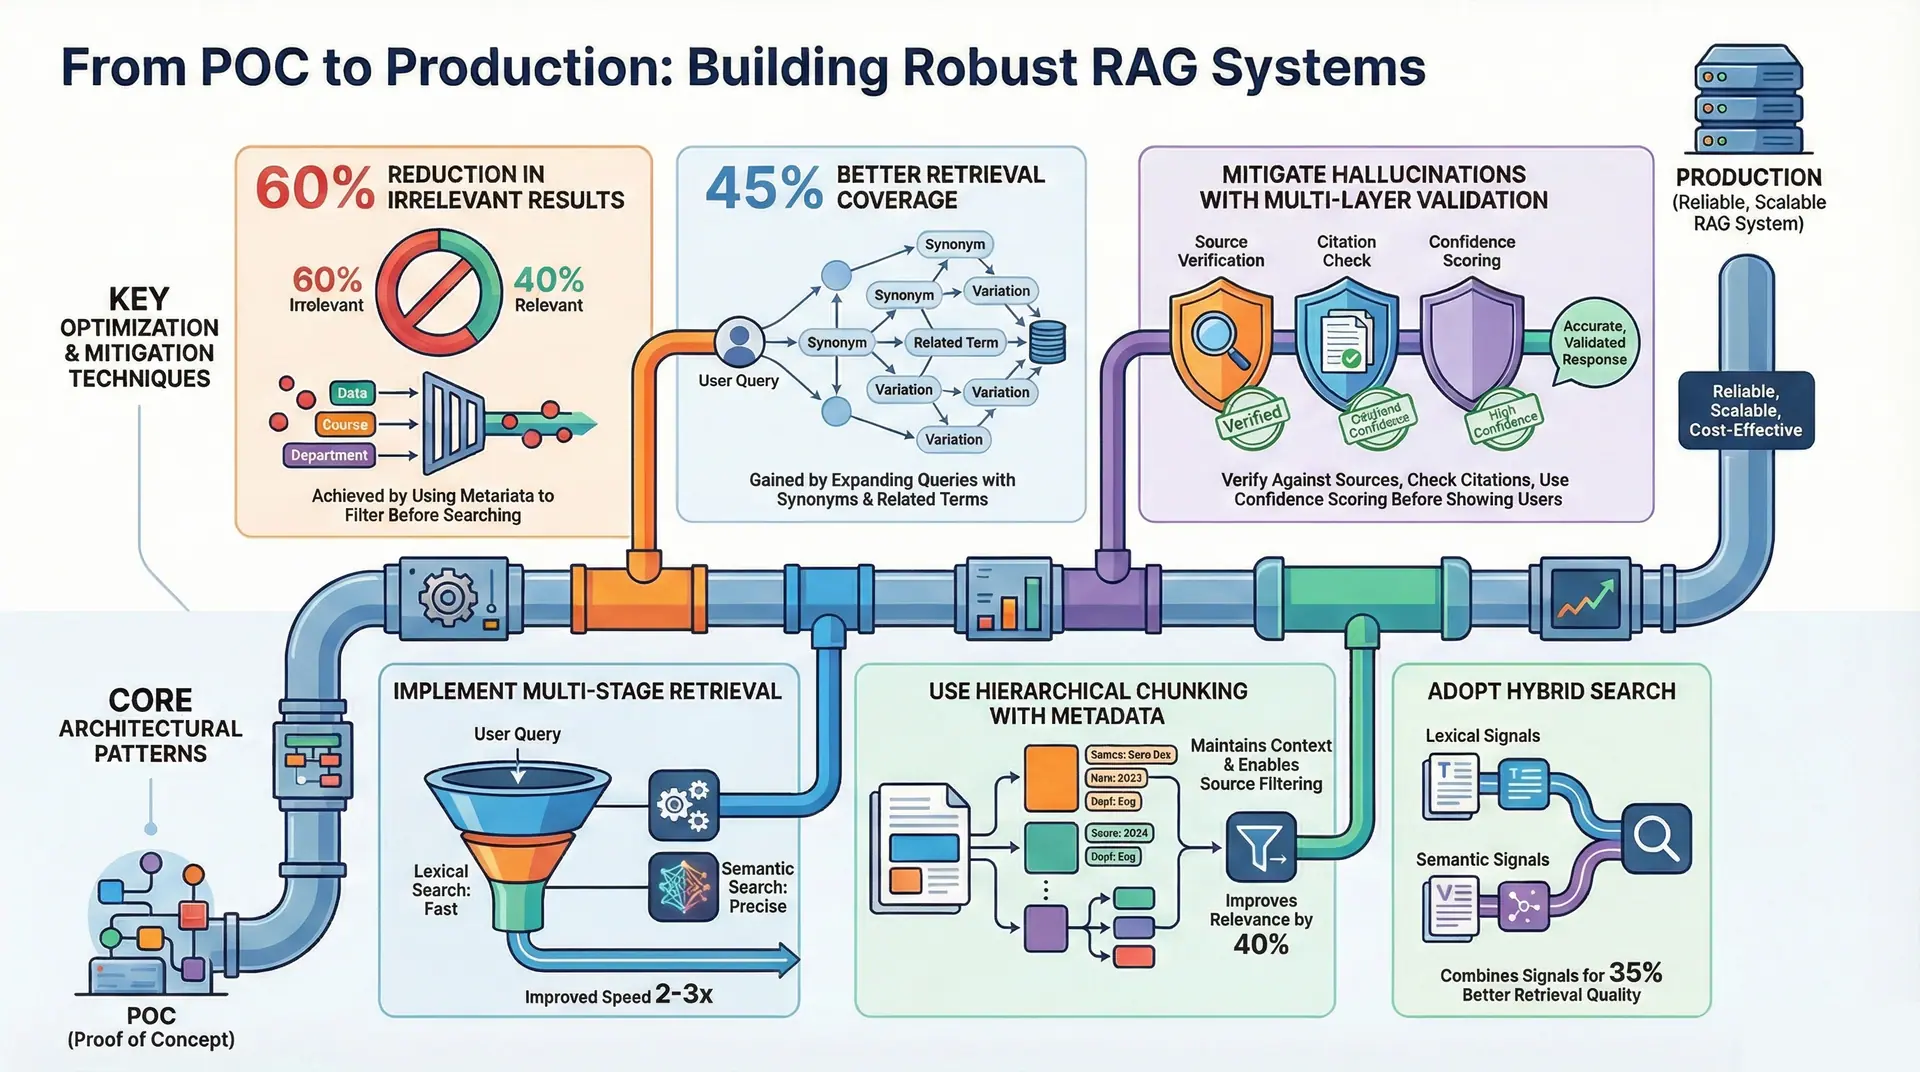
Deep dive into production-ready RAG architecture patterns, chunking strategies, embedding selection, and retrieval optimization techniques based on real-world deployments.
Comprehensive guide to LLM fine-tuning techniques, comparing LoRA (Low-Rank Adaptation) with full fine-tuning, including performance metrics and cost analysis.